Our paper "Equitable Alignment of LLMs Across Languages with Regularized Direct Preference Optimization" is accepted to EMNLP 2026!
We show that LLM alignment varies across languages and propose a regularized Direct Preference Optimization method that reduces cross-lingual alignment gaps.
Link for the paper: https://aclanthology.org/2026.findings-emnlp.121/
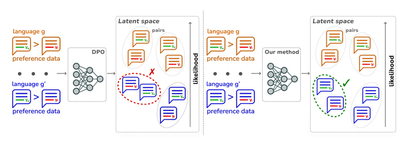
Aligning large language models with human values is a critical challenge for ensuring public safety. While methods such as Direct Preference Optimization (DPO) and Reinforcement Learning from Human Feedback (RLHF) are widely used for alignment, models often fail to maintain consistent alignment performance across languages, resulting in unequal treatment of users.
To address this issue, we introduce a regularization term in the DPO fine-tuning process that penalizes discrepancies in model behavior between languages using a bilingual corpus.
Our results demonstrate that this approach effectively reduces the alignment gap across languages following fine-tuning.
Contributions
(i) We investigate discrepancies in LLM alignment performance across languages and the resulting unequal treatment of users.
(ii) We introduce a regularization term into Direct Preference Optimization that penalizes differences in model behavior across languages using bilingual data.
(iii) We demonstrate that regularized DPO reduces the alignment gap between languages after fine-tuning.
Our findings highlight the importance of considering cross-lingual consistency when aligning multilingual language models with human values.

Christophe Gravier
Professor of Computer Science, Head of Télécom Saint-Etienne
Scientific Coordinator of the Diké Project